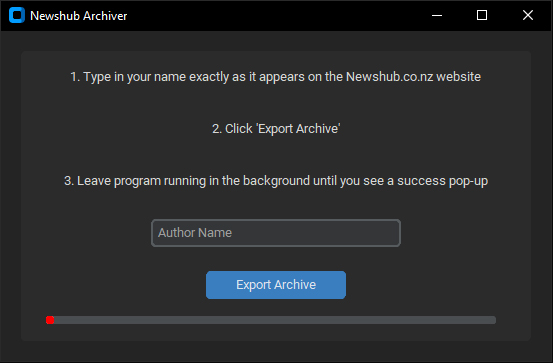
When Newshub's closure was announced in 2024, there was concern about all that history disappearing. Past and present Newshub journalists (myself included) searched for ways to save copies of our work. When I couldn't find anything, and it was clear the CMS didn't allow for mass exporting, I decided to create a custom tool.
This tool needed to be easy to use by people with minimal tech experience; I wanted journalists to search their name, click a button, and get PDF copies of their website faster than manually searching themselves. It would need a GUI and be able to run without admin permissions. It didn't need to capture every single story by a single reporter, but gain enough of them to be worthwhile.
There was a time crunch. We didn't know if the website information would be archived by any other outlets, or if it would disappear for good on the closure date.
The challenge was on.
- Python: Programming language driving the entire project
- BeautifulSoup: Python library for scraping web pages
- wkhtmltopdf: Open-source tool to convert web html pages into saved PDFs.
- CustomTkinter: Python library for creating the custom GUI
- ChatGPT: Initial research tool to narrow down the pre-existing package options to build with
I broke it into three stages: first scraping URLs from the Newshub website, then associating each link with a specific journalist, before finally converting pages to PDFs. To keep the final tool simple, I handled the first two as separate programs, so the end user only needed to enter their name in a GUI to export their stories.
My first attempt at the scraping stage was also my first failure. I wrote a script that followed every link it found starting from the Newshub.co.nz homepage, then every link those links contained, in a lengthy loop. Incredibly inefficient; it missed a lot of stories, especially older ones, and churned out duplicates. Switching to the Newshub sitemap was the fix, pulling over a million links. After stripping duplicates and known dead links, I had a database of around 700,000.
Associating links with journalists used some inside knowledge from my time as a Newshub reporter. Articles from around 2012 onwards had authors tagged as a custom class - easy to pull with a quick look in Chrome DevTools. Older articles were trickier, but there was a quirk I could exploit. When Newshub migrated its old CMS content, everything pre-2012 picked up a "Breaking" news tag. That became my flag. If there was no tagged author, the script looked for the Breaking tag, then scanned the opening sentence for the word "By" — the old byline format. If it found a name, great. If not, the article was marked authorless. The script ran for about 48 hours with occasional restarts, followed by some manual clean-up to remove stories credited to "Newshub Staff" or individual shows. Final count: around 70,000 links.
The last piece of the puzzle was a GUI for distribution. Fellow ex-Newshub journalist Dan Satherley helped extensively with testing - he's very good at breaking things. After a week of debugging, we had something that ran without admin permissions (important for people most likely running it on work computers), packaged it as a .exe, wrote a short guide and sent it out.
Dozens of reporters were able to use it, which I'm glad about - but it wasn't perfect. The PDF formatting was wonky, and a lot of manual work went into cleaning the URL list before distribution.
The two obvious improvements: a better PDF capture (screenshots of the pages would preserve formatting far better than the current method), and a smarter scraper that could find a reporter's stories and save them in one pass without generating so many duplicates.
This was my first real project after leaving news to study engineering. Overall, I'm happy with how it came out.